
When cloud computing began its rise to power, most technology experts and technology providers cited its cost-effectiveness as one of the critical benefits of the cloud. However, have you noticed that, over time, cost efficiency is rarely cited among the key advantages of cloud technologies?
That’s because many companies actually overspend on the cloud. Tracking cloud expenses becomes a big challenge, especially for companies that scale rapidly.
Fortunately, there is a solution to this problem. FinOps and cloud cost optimization have become increasingly important trends in the modern technology domain. In this article, we will discuss FinOps, its common pitfalls, best practices, and proven strategies in more detail.
The Cloud Cost Trap
One of the main reasons behind cloud costs spiraling out of control is the so-called cloud cost trap. Most cloud systems can grow exponentially due to their flexibility and integration with multiple off-the-shelf resources. In such conditions, tracking the entire system and its cost becomes a challenging task.
The most common cloud cost traps are associated with the following:
- Development environments that are not shut down on time
- Overprovisioning of instances
- Growing storage bills associated with unused snapshots and old backups
- Duplicated resources, such as idle test clusters.
FinOps best practices for cloud cost optimization help companies address these cloud traps specifically.
Why Cloud Cost Optimization Matters
According to IDC, cloud spending will exceed $1.61 trillion by 2028. As more and more companies invest in cloud-based services, the situation may spiral out of control. The best way to improve financial dynamics on different levels is by employing FinOps and cloud cost optimization.
While this approach may seem challenging, it can be handled much more efficiently with the help of managed cloud solutions experts. At least, specialists with significant hands-on experience will help you deal with common cloud cost challenges.
Common Cloud Cost Challenges
We at AppRecode worked with many companies that required optimizing their cloud spending. From our experience, the most common problems faced by such organizations include:
- Lack of tools and practices for real-time cost visibility
- Lack of organization and centralization in cloud usage
- Complexities of pricing models offered by major providers
- The abundance of waste and idle resources
- Multi-cloud complexities
- Siloed workflows within companies, which leads to a lack of accountability across engineering teams.
FinOps Best Practices for Cloud Cost Optimization
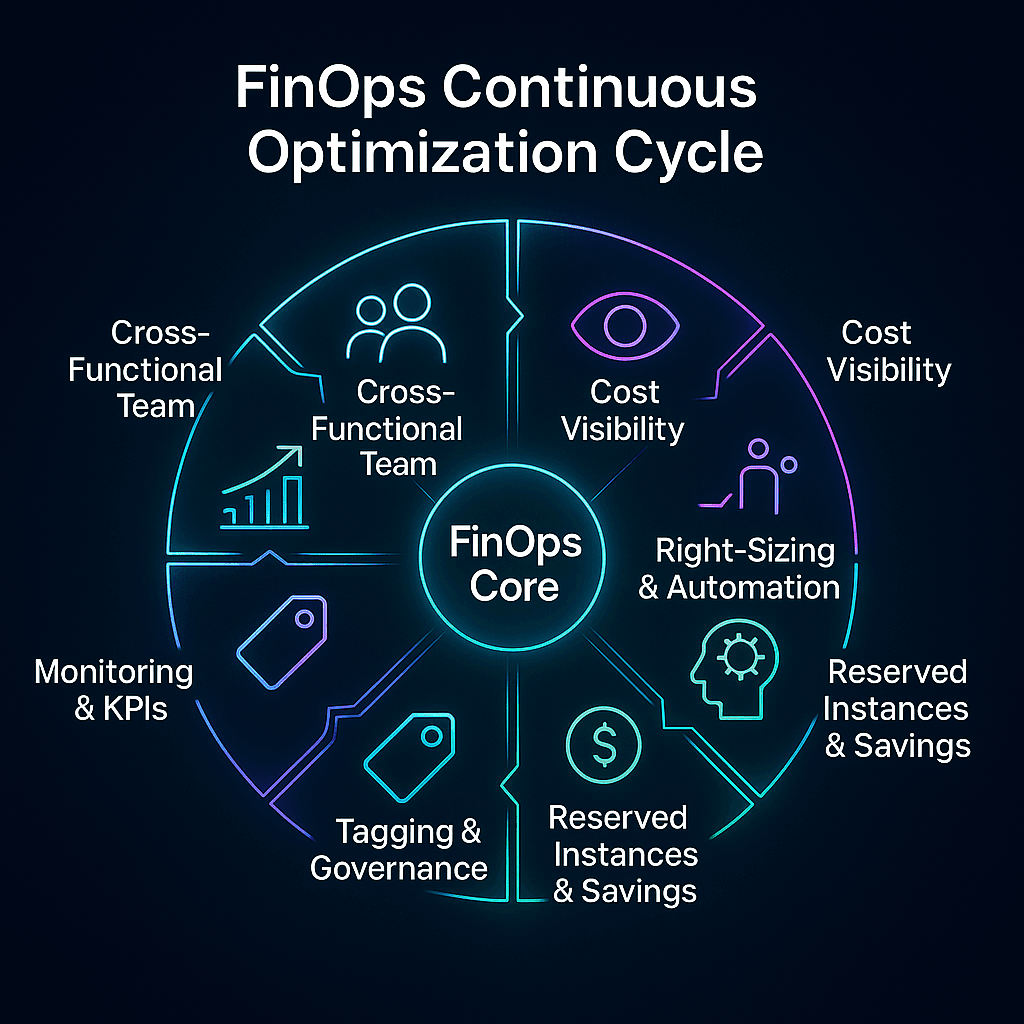
We at AppRecode have successfully built and implemented multiple FinOps cloud cost optimization strategies tailored to the needs of different businesses. They typically include the following steps.
1. Establishing a cross-functional FinOps team
It is important to break the silos within the company. This means that the FinOps team should involve engineers, finance specialists, product teams, etc. The cooperation should be based on complete transparency and efficient data exchange.
2. Ensuring real-time cloud cost visibility
Cloud cost visibility is the pillar of all FinOps initiatives. To achieve it:
- Use tools like Kubecost or AWS Cost Explorer
- Ensure cost visualization
- Enable tagging policies for all resources.
3. Right-sizing and automating resource management
Make sure that none of your instances is over- or under-provisioned. To deal with this issue:
- Rely on recommendations from AWS Compute Optimizer or Azure Advisor
- Apply auto-scaling policies
- Schedule non-production shutdowns during off-hours.
4. Using reserved instances and saving plans
Reserved instances typically help you save significant costs compared to on-demand pricing. Also, research saving plans from the major cloud providers, such as AWS, Azure, and GCP. Sometimes, they offer extremely flexible and cost-effective models.
5. Building a cost-aware engineering culture
Make sure that your engineers work in accordance with FinOps best practices for cloud cost optimization. To raise their awareness:
- Integrate cost metrics into CI/CD pipelines
- Educate teams on unit economics
- Praise your employees for their adherence to cost-effectiveness.
6. Automating tagging and governance
Ensure efficient tagging and cleanup rules. Tools like Cloud Custodian and Terraform may come in handy.
7. Monitoring and reporting KPIs
Track metrics such as:
- Cost per customer or service
- Utilization rates
- Cost of idle resources
- Forecast accuracy.
Expert Insights
FinOps should be integrated into the engineering mindset, not treated as an afterthought. Successful organizations are dedicated to FinOps practices across all operational levels. Starting from cloud migration advisory services to continuous maintenance, they focus on preventing things from getting expensive.
FinOps Cloud Cost Optimization Strategies
Let’s look deeper into the most effective FinOps strategies for practical, measurable impact.
1. Set up cloud cost allocation and tagging
Tagging is the foundation of FinOps. Every resource should have metadata that defines:
- Owner or team
- Environment (dev, test, prod)
- Project or application
- Cost center or budget code
Tools like AWS Tag Editor or Azure Policy can enforce tagging compliance automatically.
2. Build a unified cloud cost dashboard
Centralize cloud data from all accounts and providers into one dashboard.
You can use:
- CloudHealth by VMware
- Apptio Cloudability
- Kubecost (for Kubernetes)
- FinOut or Harness Cloud Cost Management
These dashboards provide real-time visibility into cost trends, anomalies, and forecasting.
3. Integrate FinOps into CI/CD workflows
An excellent choice is merging FinOps with DevOps. How does it work in practice?
Here is a practical example:
- During deployment, the pipeline checks for compliance with cost policies.
- Engineers get alerts if their code triggers high-cost configurations.
Tools like Infracost can estimate infrastructure costs directly in pull requests — preventing expensive changes before they’re deployed.
4. Use AI for predictive cost optimization
With artificial intelligence trained for cloud cost optimization, you can:
- Forecast monthly costs based on usage trends
- Detect underutilized resources automatically
- Predict traffic spikes and adjust autoscaling in advance.
Solutions like Densify, CloudZero, and Spot.io use machine learning to recommend optimal configurations.
5. Implement showback and chargeback models
Give each team ownership of their spending by showing the direct cost impact of their applications.
- Showback: Teams see their usage and costs, but don’t get billed.
- Chargeback: Costs are directly allocated to teams’ budgets.
This approach will help you establish a culture of responsibility within the company.
6. Automate cost optimization workflows
Automation reduces human error and ensures continuous cost control. Here are some examples:
- Automatically delete unused snapshots after 30 days.
- Turn off dev environments outside working hours.
- Downsize idle VMs automatically after 7 days of low usage.
Tools like Cloud Custodian, Terraform, and Ansible can enforce these rules.
Make sure to apply automation for regular monitoring, but also apply regular cloud cost audits for deeper insights into your spending patterns.
7. Optimize Kubernetes costs
Kubernetes adds flexibility but also complexity to cloud billing.
FinOps for Kubernetes should include:
- Using Kubecost to track pod-level spending.
- Implementing Vertical Pod Autoscaling (VPA) to right-size resources.
- Limiting resource requests and limits in YAML configurations.
- Removing idle namespaces and orphaned volumes.
8. Prioritize multi-cloud and hybrid optimization
When using multiple providers:
- Standardize cost metrics across clouds.
- Centralize reporting with multi-cloud tools (e.g., CloudBolt, Apptio).
- Move workloads dynamically to where they’re most cost-efficient.
How AppRecode Helps Companies Implement FinOps
At AppRecode, we help enterprises translate FinOps principles into measurable business value. Our specialists work at the intersection of engineering, finance, and strategy to ensure your cloud investments deliver maximum returns.
Our FinOps services include:
- FinOps assessment
- FinOps framework implementation
- Tool integration
- Continuous optimization.
With our help, a U.S.-based healthcare startup got an efficient monitoring solution that provides complete control over their pipelines and their costs. For more examples of our efficient work, check out our Clutch profile.
Let’s build a FinOps strategy that scales with your business!
Contact AppRecode for a free FinOps readiness assessment today.
Start HereFinal Thoughts
FinOps cloud cost optimization is not a cost-cutting exercise — it’s a transformation in how companies think about cloud economics. It empowers teams to make informed decisions, turning financial accountability into a shared cultural value.
When engineers understand the business impact of every resource, and finance teams understand the technical context behind every invoice, the cloud becomes not a cost center, but a value engine.
Whether you need help with cloud security managed services or efficient cost monitoring for your cloud infrastructure, we at AppRecode are ready to help!
FAQ
What’s the difference between FinOps and traditional cloud cost management?
Traditional cost management usually starts after the bill arrives. Finance sees a number, compares it with a budget, and asks why spend went up. That can help with control, but it is late. By the time the invoice is reviewed, the workload has already run, the storage has already grown, and the expensive architecture decision may already be part of production.
FinOps moves the conversation earlier and makes it shared. Engineering, finance, product, procurement, and business owners look at cloud usage while decisions are still being made. The goal is not only to reduce spend. It is to understand which cloud costs create value, which costs are waste, and which tradeoffs are worth making for reliability, speed, security, or growth.
The FinOps Foundation describes the practice through an iterative Inform, Optimize, and Operate lifecycle. In the Inform phase, teams make cost and usage visible and allocate them to owners. In Optimize, they act on waste, rightsizing, rate options, and architecture choices. In Operate, they track policies, KPIs, forecasts, and behavior over time.
So the difference is timing and ownership. Traditional cost management often asks, “Why did we spend this much?” FinOps asks, “Who owns this spend, what value did it produce, and what decision should we make next?” That makes cloud economics part of daily engineering and product work, not a monthly finance surprise.
How do FinOps best practices improve cloud ROI?
A good way to think about ROI is this: cloud spend is not bad by itself; unexplained cloud spend is bad. If a SaaS team pays more because it added customers and processed more requests, that may be healthy. If the same bill grows because staging runs at production size, logs are kept forever, and ten old volumes are still attached to nothing, that is not growth. That is leakage.
FinOps improves ROI by separating those two situations. First, it gives teams a cleaner view of where money is going. Owners, tags, budgets, and anomaly alerts make the bill less mysterious. A product manager can see the cost of a feature area. An engineer can see when a deployment changes infrastructure cost. Finance can see whether a forecast is believable.
Then the team can choose the right action. Maybe the fix is simple cleanup. Maybe a database needs rightsizing. Maybe storage needs lifecycle rules. Maybe a steady workload should use a commitment discount. Or maybe the answer is to keep spending because reliability or customer growth justifies it.
The real ROI improvement shows up in unit economics. Track cost per customer, order, API call, model run, or data pipeline run. If that number improves while the product grows, FinOps is doing useful work. It turns the cloud bill from a scary total into a set of decisions people can actually manage.
Which tools are best for FinOps automation and visibility?
I would not pick a FinOps tool from a generic “top ten” list. The right choice depends on the problem in front of you. If the team cannot explain last month’s AWS bill, start with AWS Cost Explorer and AWS Budgets. If the company is mostly on Azure, use Azure Cost Management and Azure Advisor first. Google Cloud billing reports and pricing calculators can also answer a surprising amount before any paid platform is needed.
The next layer depends on what hurts. If Kubernetes is the black box, Kubecost is worth looking at because it can split cluster spend by namespace, label, workload, or team. If engineers need cost feedback before infrastructure is merged, Infracost is useful inside pull requests. If leadership needs cleaner allocation, forecasting, anomaly detection, showback, or multi-cloud reporting, platforms such as Cloudability, CloudHealth, CloudZero, Harness, Finout, and similar tools can make sense.
Automation is a separate decision. Cloud Custodian, Terraform workflows, policy-as-code checks, and scheduled jobs can stop waste: old snapshots, missing tags, idle dev environments, oversized resources. But automation should not be the first move. A cleanup rule with no owner and no exception process can delete something important.
My practical order is boring but safe: make spend visible, assign owners, agree on policies, then automate the repetitive parts.
How do you integrate FinOps with DevOps workflows?
I would integrate FinOps into DevOps by starting with the moments where engineers already pause and look at a change. The pull request is the obvious one. If a Terraform change adds a larger database, another node group, a NAT gateway, or a higher storage class, the reviewer should see a rough cost estimate right there. It should feel like a normal review signal, similar to a test result or security warning.
The next place is the pipeline. CI/CD can check for boring but important things: owner tags, environment labels, approved regions, budget metadata, lifecycle rules, and resource sizes that fall outside policy. These checks need clear messages. “Add an owner tag for chargeback” is helpful. “Deployment blocked by policy 42” will just irritate people and create workarounds.
Dashboards are the third place. Engineers already look at latency, error rate, saturation, traffic, and deployment status. Put cloud cost, utilization, forecast drift, and idle capacity beside those numbers. Cost then becomes part of service health, not a finance report that appears weeks later.
Retrospectives help too. If an incident caused a flood of logs, retries, or extra compute, talk about the cost impact. If a cost-saving change hurt reliability, talk about that as well.
The aim is not to make every engineer a finance analyst. The aim is to make cost visible while technical choices are still being made.
Can FinOps really lower costs in multi-cloud environments?
FinOps can reduce costs in a multi-cloud environment, but multi-cloud itself is not the saving. I would treat that distinction seriously. A company may need several clouds because of acquisitions, customer contracts, regional coverage, resilience, or access to a specific managed service. Those are valid reasons. “It will be cheaper because we can move things around” is a much weaker reason.
The first job is to make the bills comparable. AWS, Azure, and Google Cloud use different account structures, discount models, network charges, and naming conventions. FinOps adds a shared layer: owner, product, application, environment, and cost center labels; reports for idle spend, utilization, unit cost, forecast variance, and commitment coverage. Without that layer, people argue from separate dashboards.
Then each workload needs its own business case. A cheaper VM price may be offset by data egress, duplicated monitoring, platform engineering time, compliance checks, backup changes, or different reliability behavior. Some workloads should move. Some should stay exactly where they are.
Commitments need the same caution. Savings plans, reservations, committed use discounts, and enterprise agreements can lower rates, but they can also lock waste in place if usage shifts.
So yes, FinOps can lower multi-cloud spend. I just would not promise savings until allocation and workload evidence are clean.
What cloud costs should teams look for first when starting FinOps?
When a team is starting FinOps, I would look for boring waste before chasing sophisticated optimization. The early wins are usually not hidden in a complex financial model. They are sitting in development environments that run all weekend, oversized virtual machines, idle databases, unattached disks, old snapshots, orphaned load balancers, unused public IPs, forgotten test clusters, and storage that never moves to a cheaper tier.
Start with resources that have no clear owner. If nobody knows who owns a resource, nobody is making a conscious decision to keep paying for it. Tagging and allocation may sound administrative, but they are the foundation for every later optimization conversation. A resource with owner, environment, application, and cost center labels is much easier to discuss than a mystery line item.
Then check utilization. Low CPU, low memory, idle storage, and quiet databases may indicate rightsizing opportunities. Be careful, though. Low average utilization does not always mean a resource is safe to cut. Some systems are bursty, seasonal, or intentionally overprovisioned for reliability. Look at peak patterns and business requirements before downsizing.
After waste and utilization, look at rate optimization. Savings plans, reserved capacity, committed use discounts, and spot or preemptible capacity can help, but they work best after usage is understood. Buying commitments before cleaning up waste can lock the company into paying for resources it did not need in the first place.
How should companies measure FinOps success?
I like to measure FinOps success with a mix of money metrics and behavior metrics. Money alone is too easy to game. You can cut a bill quickly by shrinking production, freezing experiments, or making engineers clean up resources by hand. The graph may look better for a month, but the business may be worse off.
Start with the basics: allocation and ownership. What share of cloud spend has a real owner? How much is tied to a product, service, environment, or cost center? If a large part of the bill is still “unknown,” the FinOps program is not mature yet, even if a few cleanup projects saved money.
Then look at forecasting. Can teams explain next month’s spend before it happens? Are budget variances investigated quickly, or do they sit until finance asks? Predictability is valuable because cloud usage changes every day, and nobody wants the invoice to be the first warning.
Efficiency metrics should be practical: idle spend, rightsizing backlog, tag coverage, storage lifecycle usage, commitment coverage, anomaly response time, and Kubernetes request-versus-usage gaps. For product context, add unit cost: per customer, transaction, API call, data job, model run, or tenant.
Finally, check habits. Do pull requests show cost impact? Do teams review anomalies? Do product owners discuss unit economics? If yes, FinOps has moved beyond a one-time cost-cutting exercise.
How can teams avoid hurting reliability while optimizing cloud costs?
Cost optimization becomes dangerous when it is treated as a blind cut. Turning off resources, shrinking instances, reducing replicas, or deleting “unused” storage can save money for a week and create an outage the next. The safer approach is to treat cost as one design constraint alongside reliability, security, performance, and delivery speed.
Start with context. A low-utilization development VM may be an easy shutdown candidate. A low-utilization production database may be intentionally sized for peak traffic, failover, batch windows, or future growth. The same metric can mean different things depending on workload behavior. That is why optimization should involve the service owner, not only a central cost team.
Use staged changes. Rightsize one service, watch performance, then expand. Adjust autoscaling policies gradually. Test storage lifecycle rules before applying them broadly. For Kubernetes, compare requests and actual usage, but avoid setting limits so aggressively that workloads get throttled or killed during normal spikes.
Reliability-aware FinOps also needs guardrails. Define minimum capacity, error budget impact, rollback steps, and change windows for high-risk workloads. Some savings plans are architectural; others are operational. A reserved commitment may be low risk for a steady workload, while a forced downsizing campaign can be risky if done without telemetry.
The honest goal is not the lowest possible bill. It is the lowest reasonable cost for the reliability and business outcome the workload needs. Good FinOps protects value, not just budget.
“FinOps isn’t about cutting cloud costs — it’s about maximizing cloud value. When finance and engineering collaborate, every dollar becomes a driver of innovation.”
Volodymyr Shynkar, Founder at AppRecode